
HRSD Nansemond Treatment Plant - AvN Control
Through its Digital Water program, HRSD continuously seeks to optimize wastewater operations and environmental protection. Yet, advancing from existing systems (like APC/MPC or ABAC) to true continuous optimization typically requires extensive first-principles modeling and carries significant operational risk during live deployment. To overcome these deployment barriers, RLCore partnered with HDR to test RLTune™ on a digital twin of the Nansemond Treatment Plant. By acting as a dynamic, guardrailed optimization layer for AvN control, this pilot shows that a model-free agent can achieve state-of-the-art control performance without prior data, bridging the gap to safe, live-plant deployment.
The primary focus of this project is to evaluate whether RLCore can deploy a reinforcement learning-based optimization policy on a realistic digital twin of the Nansemond Treatment Plant (NTP) for AvN operations in preparation for physical plant deployment. The agent is tasked with controlling dissolved oxygen (DO) setpoints to minimize the difference between the measured AvN (or AvTIN) value and the setpoint. The overarching goal is to properly feed the partial denitrification-anammox (PdNA) zone, which in turn maintains effluent targets within operating limits, minimizes aeration energy use, and stabilizes the process under variable loads.
RLCore deployed RLTune™ as an adaptive optimization layer that continuously learns and recommends bounded setpoint adjustments. Key capabilities demonstrated include:
- Continuous Learning: Adapts automatically as influent loads, weather, biology, and equipment conditions drift over time.
- Model-Free Optimization: Operates directly on plant data without the need for a first-principles or surrogate model to initiate learning.
- Comprehensive Observation: The agent observes a wide array of constraints and variables, including influent (flow, temp), and tank conditions (DO, MLSS, NHx, NOx).
- Bounded Control Actions: Operating within strict, operator-established guardrails, all setpoint modifications stay within defined process and equipment boundaries, while the agent continuously maintains optimal DO setpoints to achieve target performance.
The intermediate results demonstrate significant success within the HDR-supplied digital twin environment, which closely mirrors the physical realities of the NTP. Key performance highlights include:
- RLTune successfully and rapidly drove improvements in AvN control on the digital twin, operating entirely without prior data.
- The system achieved state-of-the-art control after only 75 days of simulated time, proving its high sample efficiency and drastically reducing the traditional machine learning commissioning burden.
- Throughout this 75 day period, the agent is continually improving above the plant baseline. This points to a viable pathway for learning on a live plant under real operations
Conclusions
This digital twin case study establishes that an AI-driven, model-free policy can effectively track AvN targets with extreme sample efficiency. The simulated deployment achieved state-of-the-art control in just 75 days with no prior operational data. It validates that RLTune can effectively complement HRSD's existing control systems by providing a continuously adapting, guardrailed optimization layer.
Next Steps
The primary next step is the real-world physical deployment at the Nansemond Treatment Plant (NTP), moving beyond simulation to review guardrails, operational results, and oversight requirements in live conditions. Some of the work that will be done to prepare for physical deployment includes running simulation experiments to identify the smallest set of sensors needed for good AvN control, as well as using historical data pretraining to decrease the agent’s time-to-performance.
Initial plant deployment will leverage NTP’s parallel bioreactor trains by staging implementation: deploying the agent to a single train first during its initial learning phase before expanding across all trains once target performance is met. This structured approach allows the agent to learn under live operating conditions without risk to overall plant operations. For facilities without parallel trains, the learning phase can be safely managed using scheduled guardrails that gradually expand around existing operating procedures, ensuring a seamless and controlled transition to full agent operation.
Following successful implementation at NTP, the project aims to evaluate potential further deployment at the York River Treatment Plant. Additionally, RLCore has identified potential extensions for the agent to broaden its overall optimization scope, including controlling solids inventory to further improve AvN tracking.
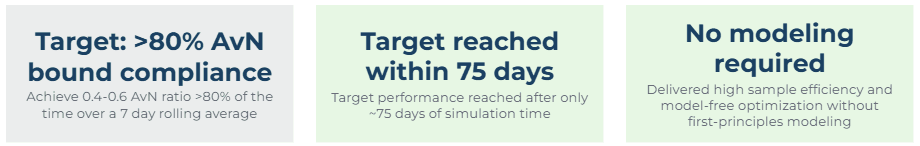
Figure 1. Percent of time within AvN compliance over a rolling 7 day window. The agent starts on 01/01 with no historical data or pretraining, and within 75 days is consistently above the 80% target threshold (1 / 2)